Imagine an API load test reporting 5,000 requests per second with p95 below a second, while a quiet synthetic browser check also passes. Those illustrative results leave a question open: does checkout remain usable under the expected surge? Run the journey while the backend is under representative load, and compare it with your field monitoring.
A fast server response and a responsive browser journey measure different parts of the experience. A load plan needs to account for both.
Two green dashboards, one missing question
Field monitoring records real user experiences, including busy periods when sampled; it is not limited to idle conditions. A synthetic probe may miss peak conditions if it is scheduled or configured that way. INP replaced FID in March 2024, and its good threshold is 200 milliseconds. Inspect your actual field distribution and sampling before deciding it misses a rush.
INP measures the latency of an interaction: you click, and it counts how long until the page visibly responds. It matters here because it is a main-thread metric, and it degrades precisely when the browser's event loop is busy running JavaScript, working through a queued re-render, doing real work. A quiet period can still contain expensive client work; time of day alone does not determine responsiveness. During the rush the same click lands behind a queue of other work, and the spinner spins while a real person waits. Check whether your monitoring sampled those conditions before treating this as an unseen failure.
The load test has the opposite blind spot. Protocol-level load, raw HTTP requests fired at your endpoints, is the right tool for one question: can the backend take the volume? It is cheap enough to reach the concurrency that actually breaks an API tier or saturates a connection pool, and it isolates server latency from everything else. But a protocol VU has no DOM, runs no JavaScript, and renders nothing, so it can report 200s in 300 milliseconds while the page those responses feed takes six seconds to become interactive. Your backend looks perfectly healthy in that test, and the customer has already closed the tab.
So you have an experience instrument whose sampling may miss the load condition you need, and another that measures load but only at the server. The question that falls through the crack is the one that actually matters on launch day: is the app still usable when it's busy?
The instrument that answers it
To measure experienced latency under load, you need something that is both a real browser and a concurrent user. That is a browser virtual user: an actual headless Chromium instance, driven through a real user journey, running alongside hundreds of other requests hammering the same backend. It renders the page, runs your bundle, and fires the same XHR waterfall a human would trigger. Then it times the thing a human actually feels, which is the gap between clicking checkout and seeing the confirmation.
These two kinds of virtual user do different jobs, and picking the wrong one either wastes money or measures the wrong thing. Protocol VUs generate volume cheaply, but they are blind to the browser. Browser VUs cost more per user and, in exchange, see everything the browser does. We wrote a fuller comparison in browser VUs vs protocol VUs; the short version is that protocol traffic creates the stress and browser traffic tells you whether a real person would notice it.
The pattern that works layers them. Use protocol VUs to push the background load, the thousands of concurrent requests that drive your infrastructure toward its ceiling. Then run a smaller pool of browser VUs replaying your real feature journeys while that pressure is on. Protocol load can stress backend capacity; browser execution adds client rendering work, and the browser VUs measure the "click to confirmation" latency while it is saturated. That number, experienced latency under concurrency, is the one your calm INP score can't produce and your protocol test can't see.
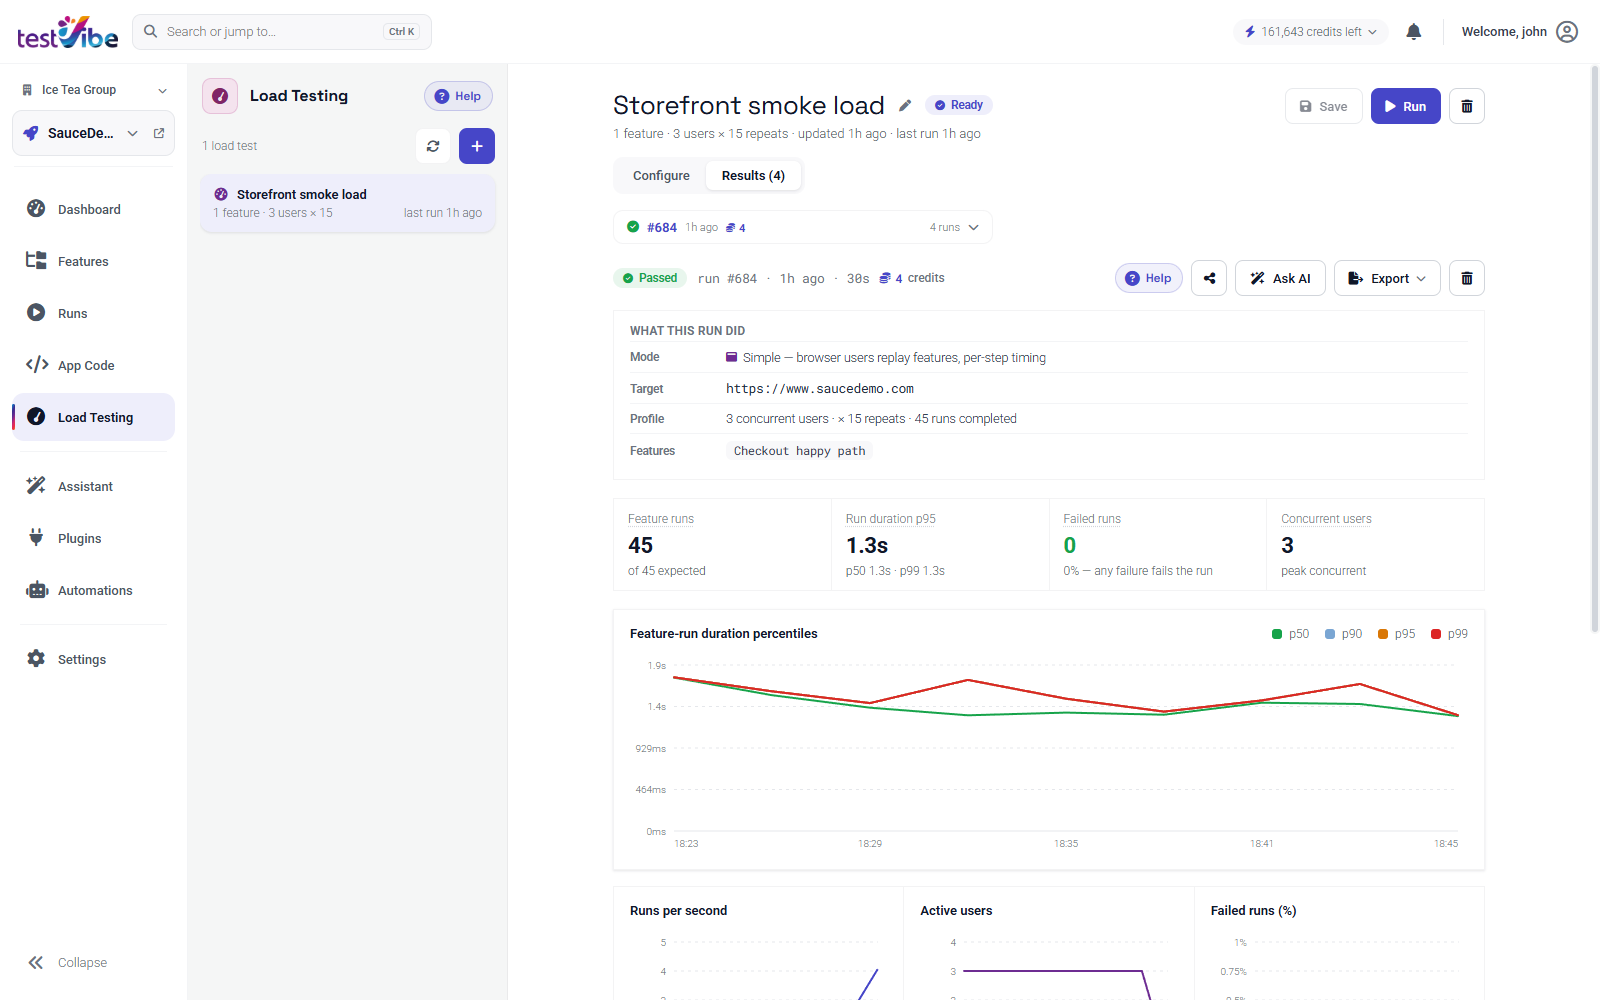
Read the slow tail of the measured interactions
Once you are measuring journey duration under load, inspect the slow tail as well as the mean. An average can look acceptable while some measured interactions take much longer.
Percentiles are what carry the experience. p50 is the median measured duration. p95 and p99 describe higher points in the duration distribution; interactions are not distinct people, and percentile estimates depend on sample size and method. The tail also degrades non-linearly: a system holding p50 steady at 120 ms can watch p99 climb from 400 ms to eight seconds as concurrency rises while the average barely twitches, so if you only watch the mean you get the launch-day surprise anyway. The statistics behind reading percentiles are the same whether you're measuring server latency or experienced latency. The difference is that browser VUs let you compute those percentiles on the number a user actually feels, per step of the journey, so you can see which interaction degrades first.
That is what matters most for input-heavy pages. INP dies under load on exactly the surfaces that do the most client-side work: a search-as-you-type field, a cart that re-renders on every quantity change, a dashboard rehydrating a SPA. A protocol test never touches that code. A browser VU runs it at concurrency and hands you the p95 of the interaction, which measures the selected journey under load. That duration is not interchangeable with field INP.
Where this sits next to your monitoring
None of this replaces monitoring; it complements it. Synthetic and field vitals describe the conditions and populations they actually measured, and you should keep watching them. Pair a pre-spike load test with continuous production monitoring so the ceiling you validated stays the ceiling you actually have. Just don't mistake a green resting score for a result, because a quiet-condition result does not establish peak-load behavior.
So measure the busy case before it's live, the same way you'd model a surge before the spike arrives instead of discovering your capacity by browning out in front of everyone. Ramp protocol traffic until you find where the backend bends, layer browser VUs on top to read experienced latency under that pressure, and watch the p95 and p99 of the interaction rather than the average of the request. The concurrency level where the tail fans out and the spinner starts spinning, not your 3 a.m. INP, is the honest answer to whether you can handle the rush.
Use repeatable traffic and browser journeys to investigate this before launch, then compare the results with what production monitoring observes.
Try it before the rush
Want to measure experienced latency under load, with real browsers replaying your real journeys as concurrent users and per-step percentiles instead of a comforting average? Get early access, or read the browser-VU breakdown to see how the two kinds of virtual user fit together.